Most creators already own more usable material than they think. The problem isn't lack of ideas. It's that years of videos, podcasts, articles, transcripts, notes, and research sit in scattered folders, old drives, CMS entries, editing timelines, and team chats, so nobody can quickly find what already exists or turn it into the next publishable asset.
That's where knowledge management best practices stop being corporate jargon and start acting like a revenue-enabling content operating system. Good KM helps a YouTuber find every strong segment on one topic across old episodes. It helps a magazine publisher reconnect archived reporting into a new package. It helps a podcast team trace recurring audience questions, approved source material, and past guest insights without starting from zero each time.
The discipline has deep roots. A major early milestone came when organizations such as Chaparral Steel, Digital Equipment Corporation, and USAA began deliberately managing explicit organizational knowledge through technology and documented processes, and the field later reached a standardization milestone with ISO 30401 in 2018, which pushed KM toward a more auditable management discipline (Springer chapter on KM history and ISO 30401). That history matters because modern systems work best when they treat knowledge as governed, reusable, and measurable.
For creators and publishers, the playbook is practical. Centralize the library. Build a taxonomy. Fix search. govern lifecycle decisions. Document how work gets done. Use AI with human review. Repurpose intelligently. Adapt by platform. Measure what matters. Listen to audience signals. Contesimal is one example of a platform built around that exact challenge: classifying, organizing, searching, and collaborating across historical content libraries so past work can keep producing new value.
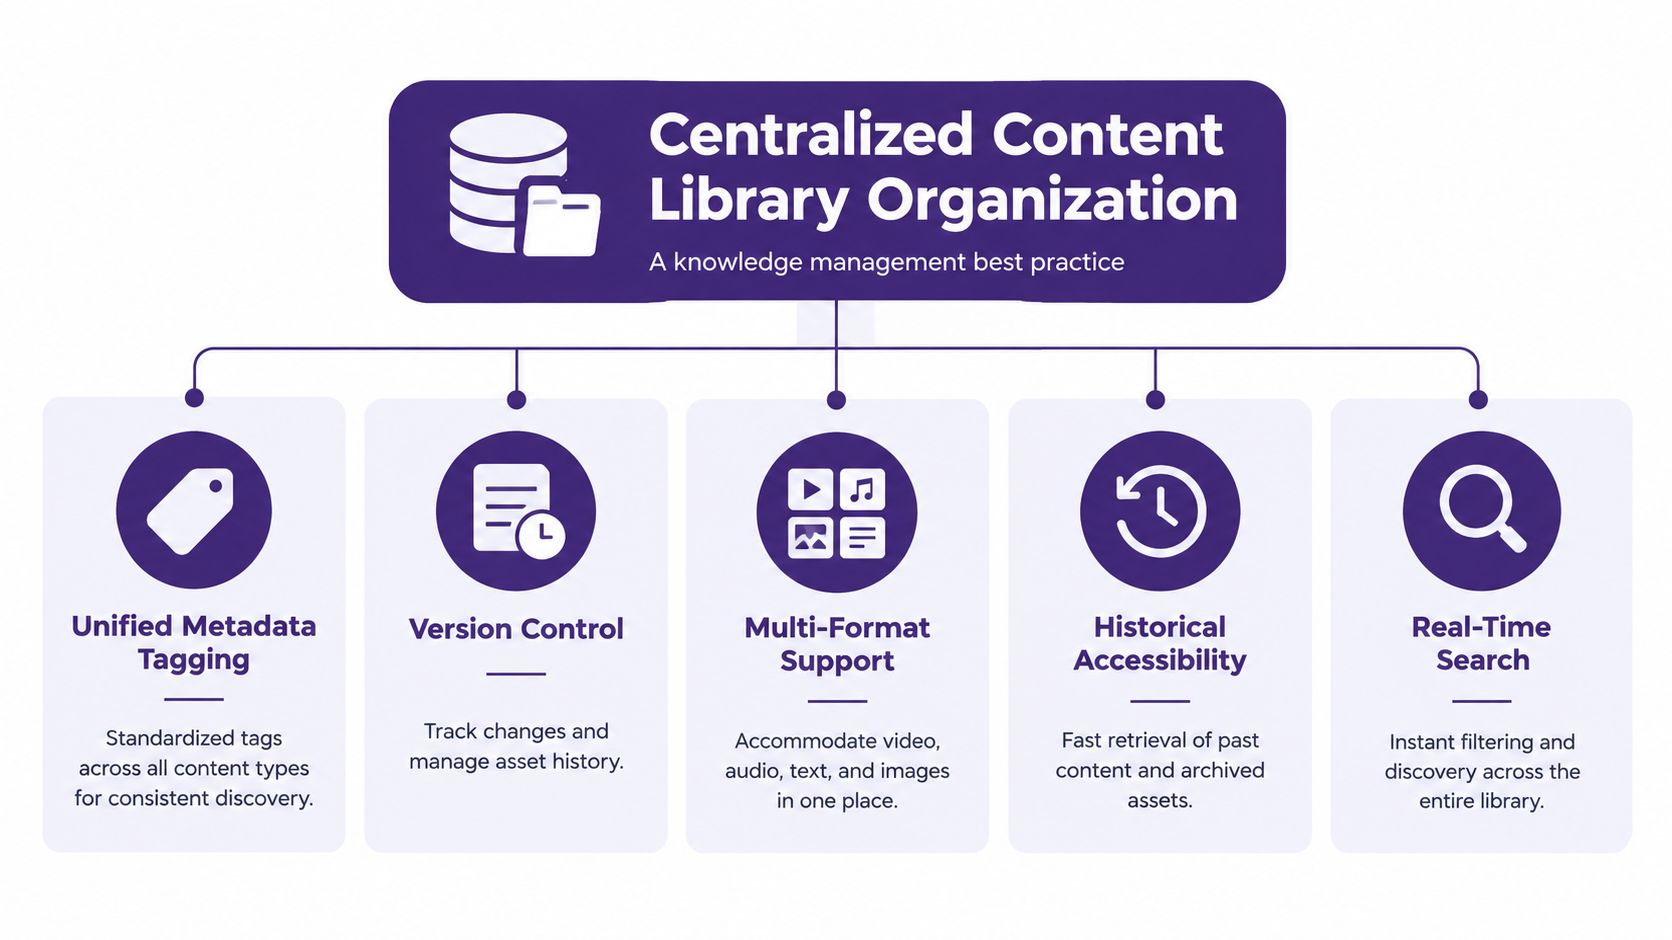
1. Centralized Content Library Organization
Scattered archives kill reuse. If your podcast transcripts live in one app, raw video on external drives, article drafts in Google Docs, and research in Slack threads, your team doesn't have a library. It has a scavenger hunt.
The fix is boring and powerful. Put priority assets into one organized repository that spans formats and time periods. For a publisher, that could mean archived features, photography, rights notes, and update history in one place. For a YouTube team, it could mean finished uploads, transcripts, b-roll, thumbnails, scripts, sponsor reads, and performance notes connected under one record.
What centralization changes
A recent survey of 307 knowledge management leaders and practitioners across more than 20 industries found that successful initiatives often focused on document search, retrieval, delivery, and access enhancements, including centralizing document collections, taxonomy and portal integration, RSS feeds, and standardized quality-control procedures (2023 state of knowledge management survey). That aligns with what content teams run into every day. Centralization doesn't just tidy the house. It makes retrieval fast enough to support publishing.
Use a phased approach:
- Start with high-value assets: Bring in evergreen videos, flagship podcast episodes, cornerstone blog posts, and source-rich research first.
- Connect related materials: Keep transcripts, clips, artwork, notes, and published versions tied to the same parent asset.
- Set access on purpose: Editors, producers, and freelancers need different visibility and edit rights.
Centralization isn't about moving every file on day one. It's about making your most reusable knowledge easy to find this week.
A podcast network can tag and centralize older episodes to identify recurring themes worth reviving. A news team can reconnect related archive pieces to produce fresh topic hubs. A creator with years of uploads can finally see which old themes deserve a sequel instead of guessing the next idea from scratch.
2. Layered Taxonomy and Smart Tagging Systems
Taxonomy decides whether your archive earns its keep or sits there like cold storage.
A content library becomes revenue infrastructure when assets can be retrieved in more than one business context. Editors need topic and format. Sales and partnerships may need audience, sponsor fit, rights status, and proof points. Producers need series, guest, clip potential, and update priority. One asset should support all of those views without being duplicated five times.
That changes how tagging gets designed. The goal is not descriptive labeling for its own sake. The goal is to answer the retrieval questions that lead to new output, faster packaging, and better reuse across channels.
A practical setup uses layers.
Start with a stable top layer that rarely changes: content type, primary topic, brand or publication, language, rights, and lifecycle status. Add a second layer for workflow and repurposing signals: source-rich, quote-heavy, clip-worthy, seasonal, expert-led, beginner-friendly, sponsor-safe, update-needed. Then add a third layer only where the business model demands it, such as funnel stage for a B2B publisher, curriculum level for an educator, or franchise and character tags for an entertainment team.
For a closer look at how to structure those layers, this guide to content tagging and taxonomy is directly relevant.
A creator with 200 podcast episodes might only need 20 to 30 controlled tags at first. A media company with newsletters, video, social clips, and licensed archive footage may need faceted tagging with stricter governance. Both can fail the same way. They add tags faster than they define them, and the system turns into private shorthand.
The trade-off is real. Too few tags and good material stays buried. Too many tags and nobody applies them consistently. I usually recommend testing taxonomy against actual production requests, not hypothetical neatness. Ask what your team tries to pull every week: "Find all strong clips for founders," "Show me evergreen assets we can refresh for Q4," "Which interviews mention pricing objections?" If the taxonomy cannot answer those questions quickly, it is decorative.
Some teams should sketch relationships before they formalize metadata. Tools with visual workspace features can help editors map clusters, recurring themes, and derivative paths such as article to thread to clip to newsletter.
Good tagging also needs rules. Use singular or plural consistently. Define when a tag is required versus optional. Ban vague labels like "great convo" or "misc." Merge synonyms before they spread. Review tag usage monthly, especially after launching a new series or content line.
That discipline pays off in output, not just tidiness. A publisher can spot underused topic clusters and package them into a new series. A solo creator can pull every source-rich asset on one theme and turn it into a workshop, lead magnet, or sponsored content package. Taxonomy is the operating logic that turns old work into inventory for new work.
3. Search Optimization and Metadata Standards
Search is the stress test for your knowledge system. A library can look organized in folders and still fail the moment an editor needs three approved clips on pricing, a sales marketer needs past objections by segment, or a newsletter writer needs every source tied to one theme.
That failure is expensive. Teams remake work they already own, miss reusable assets, and publish slower across every channel.
Good search starts before anyone types a query. It starts with a metadata minimum that makes assets findable, filterable, and safe to reuse. For many creator and publisher teams, that baseline includes title, format, primary topic, audience, owner, rights or approval status, publish date, transcript or summary, and links to related derivatives such as clips, threads, newsletters, and follow-up articles. Those fields turn an archive into working inventory.
The practical question is simple: what should someone be able to retrieve in under a minute?
For a video team, the answer might be every moment where a guest discussed churn, with transcript snippets and reuse status attached. For a B2B publisher, it might be all assets aimed at operations leaders, updated within the last year, with claims already approved. Search standards should be built around those retrieval jobs, not around whatever fields happen to come with the tool.
One source on structured reuse argues for fields like creation date, last use date, compliance verification timestamp, owner assignment, and version control so customized outputs stay separate from master assets (structured reuse workflow fields and version control). You do not need every field in every system. You do need enough structure to answer three things fast: what this asset is, who can use it, and what can be made from it next.
A few rules keep search useful without turning metadata into admin theater:
- Set a publish gate for required fields. Assets without core metadata should not enter the active library.
- Support real query language. Map synonyms and common phrasing such as “short-form video,” “Reel,” and “clip” if your team uses them interchangeably.
- Index the text, not just the title. Transcripts, summaries, speaker names, claims, and callouts often matter more than file names.
- Review search misses and weak results. They reveal where metadata is thin, naming is inconsistent, or audience labels are too broad.
I also recommend separating descriptive metadata from operational metadata. Descriptive fields help people find the asset. Operational fields help them decide whether to use it. That split matters because “podcast interview about onboarding” and “approved for paid promotion” answer different questions, and both affect revenue-producing reuse.
Search should return assets that are usable, not merely adjacent. That is the standard. When teams hit it, existing content starts feeding new content across platforms instead of sitting in cold storage.
4. Content Lifecycle and Asset Governance
A content library makes money only if people can trust what they find.
That trust breaks fast when a sales team pulls an old case study with expired claims, a producer clips footage that cannot be reused on another platform, or an editor revives a strong article that now points to dead offers. Governance fixes that by attaching decisions to assets after publication, not just before it.
The practical question is simple: what should this asset do for the business now?
Some assets should stay in circulation because they still attract the right audience and support current offers. Some deserve a scheduled refresh because the framing works but the examples, links, or product details have aged. Others belong in cold storage for recordkeeping, with clear labels that keep them out of day-to-day reuse. Teams that want a more formal model can use this guide to content lifecycle management as a reference.
I have found that ownership matters more than intent. If nobody owns the reuse decision, old content keeps floating around by inertia. That is how archives turn into liability instead of fuel.
A lean status model usually does the job:
- Active: current, approved, and easy to repurpose
- Refresh: strong base asset, but needs updates before reuse
- Reuse cleared: legally, editorially, and commercially approved for adaptation
- Archive: kept for reference, not for active promotion
- Retired: preserved if needed, blocked from reuse
The point is not administrative neatness. The point is speed with judgment.
A magazine publisher might flag evergreen explainers for annual review and retire service pieces tied to outdated regulations. A video team might separate "great performance clip" from "great performance clip with limited rights," because those are very different assets operationally. A podcast network might keep a back-catalog episode live, but mark only selected segments as safe for thematic compilations, paid promotion, or YouTube reuse.
That distinction matters because lifecycle governance is where knowledge management starts acting like a revenue system. It connects the archive to new production. Teams can see which assets are safe to repackage, which ones need editorial work first, and which ones should stay out of circulation entirely. Without that layer, search may return relevant assets that still create legal, brand, or conversion risk.
Keep preservation and discoverability separate. Historical material still has value, especially for research, compliance, and retrospective content. It should not compete with approved source material when a creator needs usable inputs fast.
Good governance does not make the library smaller. It makes the library dependable enough to produce from.
5. Documentation, Knowledge Base, and Process Standardization
A content operation becomes fragile when key workflows only live in one person's head. If the editor who knows the title formula, publishing checklist, clipping criteria, and thumbnail rules disappears for a week, production stalls.
Documentation fixes that. Not glamorous PDFs nobody reads. Useful process knowledge that's searchable, current, and attached to the moments where people need it.
Standardize the repeatable parts
The strongest teams document the boring work so they can spend more energy on the creative work. That includes editorial standards, scripting templates, guest prep docs, rights review steps, formatting rules, fact-checking procedures, distribution checklists, and repurposing playbooks.
A formal knowledge base also supports measurable outcomes. In the 2017 State of Knowledge Management survey, 43% of respondents said their organizations could improve employee productivity by 30% or more if knowledge were shared more efficiently, and 14% said the potential improvement could be 50% or more (2017 State of Knowledge Management survey PDF). That's a strong reminder that documentation isn't clerical overhead. It reduces repeat work.
This guide on how to build a knowledge base is worth keeping handy if your system still lives across random docs and private bookmarks.
Write down the decision logic, not just the final template. Teams move faster when they know why the rule exists.
A YouTube channel can standardize intros, chapter structure, and thumbnail review. A publishing team can document source validation and update triggers. A podcast operation can create one reliable process for recording, editing, clipping, and distribution. The more often a task repeats, the more expensive it is to leave undocumented.
6. Collaborative Content Intelligence and Human-AI Collaboration
AI can help sort, cluster, summarize, and surface patterns across a large content archive. It can't carry editorial judgment on its own. Teams get the best results when AI handles first-pass organization and humans handle context, quality, and final decisions.
That split matters because the biggest KM failures usually aren't technical. A 2024 synthesis of 44 hindering factors found that major barriers included lack of motivation, unclear job descriptions, and low familiarity or confidence, with obstacles spanning personal, organizational, technical, environmental, and socio-technical factors (2024 synthesis of KM barriers). In other words, better AI doesn't fix vague ownership or weak habits.
Use AI where the work is repetitive
Strong applications for creator teams include transcript tagging, theme clustering, related-asset suggestions, draft summaries, quote extraction, and archive discovery. An editor can review those outputs, reject weak suggestions, and promote useful ones into the official system.
That workflow helps in real situations:
- Research teams can surface overlapping themes across interviews and notes.
- Publishers can identify archived topics worth revisiting.
- Video creators can spot clip candidates inside long-form recordings.
- Content marketers can connect approved references to upcoming drafts.
Train the team on what the system should and shouldn't do. If people assume AI is authoritative, errors spread. If they treat it like a fast research assistant with supervision, it becomes useful.
7. Multi-Format Content Expansion and Atomization
A content archive starts paying back faster when each asset is stored as parts, not just as a finished file.
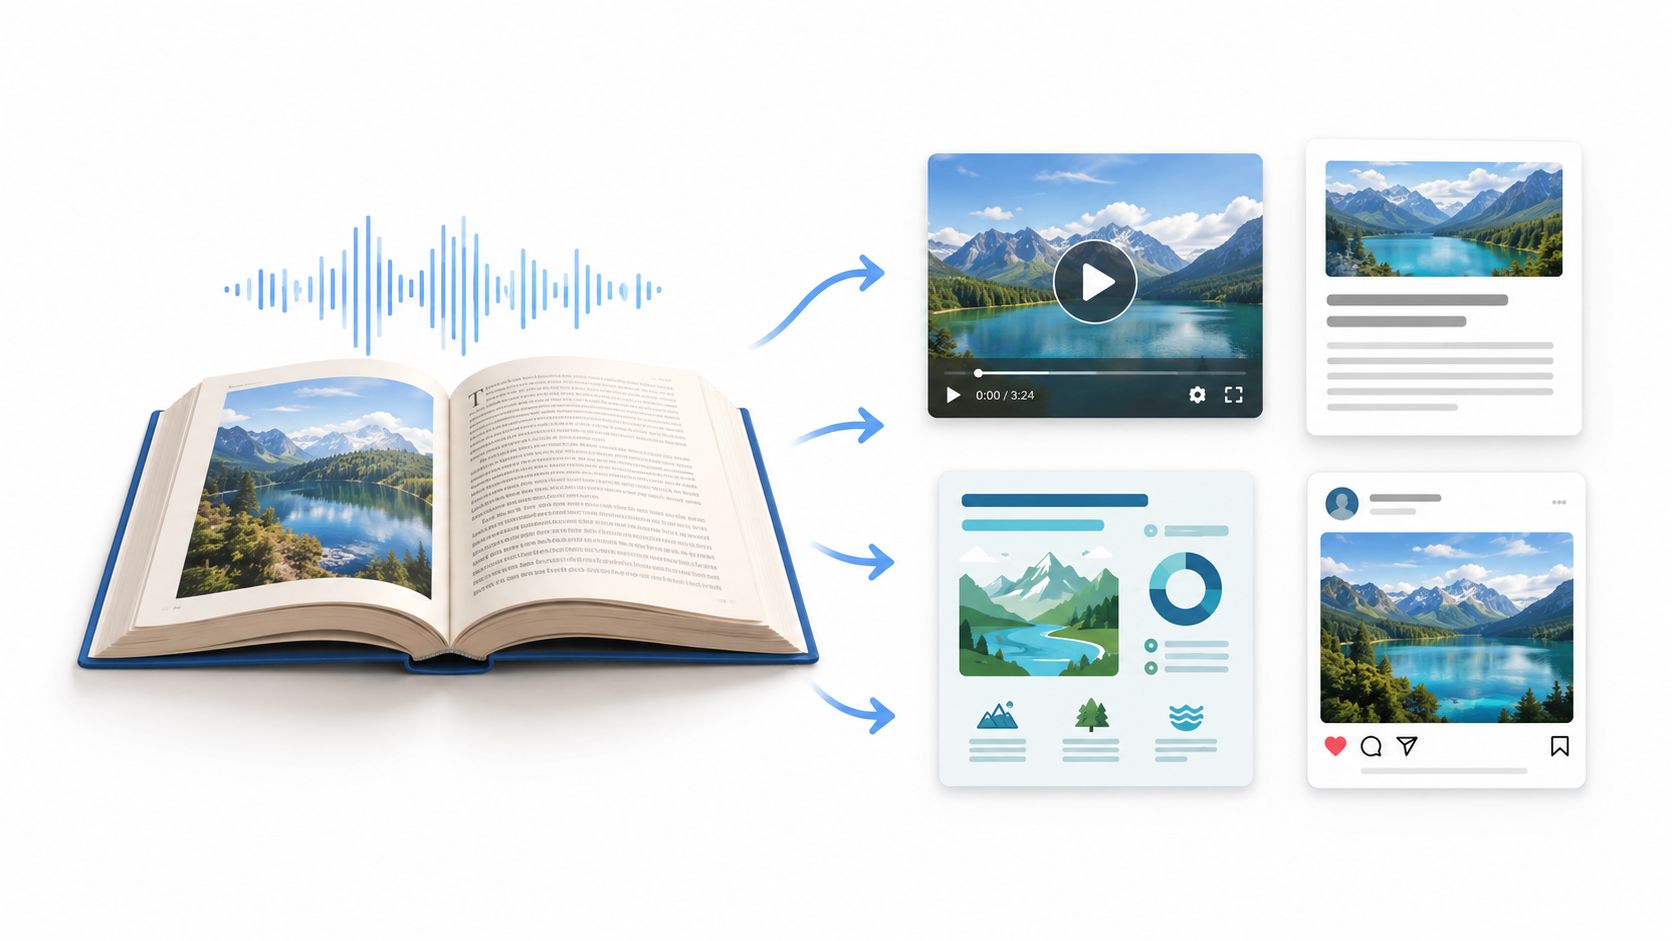
That changes how teams produce. A recorded interview is not only a podcast episode or article draft. It is also a bank of claims, examples, timestamps, quotes, objections, visuals, and story turns that can feed future work across channels. Knowledge management matters here because the system has to preserve those pieces well enough that an editor, producer, or marketer can find and reuse them without rebuilding the context from scratch.
The practical shift is simple. Stop treating repurposing as a late-stage promotional task. Treat atomization as an editorial design choice at the moment of capture.
Here is what that looks like in production:
- During recording: ask modular questions that can stand alone as clips, excerpts, or sidebar sections.
- During editing: mark clean extraction points, strong pull quotes, and examples with clear audience value.
- During publishing: connect every derivative asset back to the parent source so the team can trace what came from where.
- During archiving: store the transcript, summary, chapters, tags, rights notes, and reusable media elements together.
A 90-minute creator interview with weak structure often produces one decent upload and a messy transcript. The same interview with clear segments, named themes, and logged moments can support short video, newsletter commentary, a blog post, sales collateral, and research for a follow-up piece. That is the difference between a passive library and a revenue-enabling content operating system.
The trade-off is upfront effort. Producers need to log moments. Editors need naming discipline. Someone has to decide whether a fragment is reusable or just technically extractable. I have seen teams over-atomize and fill the library with thin fragments nobody wants. The fix is to save units that carry meaning on their own, not every sentence or clip.
One industry summary notes that a single blog post can be turned into multiple assets across formats (content repurposing summary). The useful takeaway is narrower. Good source material usually contains more publishable units than the team currently captures.
A few asset types tend to travel well:
- Explanation units: definitions, frameworks, step-by-step guidance
- Proof units: examples, case references, before-and-after moments
- Opinion units: sharp claims, contrarian takes, strong conclusions
- Story units: anecdotes, turning points, mistakes, lessons learned
Publishers can split a long feature into a briefing, subscriber email, quote cards, and a follow-up analysis. Video teams can turn one webinar into clips, show notes, FAQs, and a text article. B2B marketers can pull approved insights from a customer call and reuse them in social posts, pitch decks, and nurture content.
The system earns its keep when every derivative asset points back to the source, and every source is stored in a way that makes the next format faster to produce.
8. Cross-Platform Content Adaptation and Localization
Cross-platform adaptation is where a content archive starts producing revenue instead of just storing effort.
A useful source asset should be able to travel. But it should not arrive unchanged. Every channel has its own mechanics, audience expectations, and failure modes. A sharp webinar clip can earn watch time on YouTube and fall flat on LinkedIn because the setup is too slow. A strong article can become a weak newsletter if nobody rewrites the opening around the subscriber's immediate problem.
The teams that handle this well do not ask, "How many places can we post this?" They ask two tighter questions: "What job is this asset doing on this channel?" and "What has to change so the same idea still feels native?"
That requires more than a file library. It requires stored context. If the knowledge system captures audience segment, buying stage, geography, source format, approved claims, visual dependencies, and tone, editors can adapt with speed and control instead of starting from zero each time.
Here is a practical way to make those decisions:
- Keep the source truth fixed. The core claim, facts, examples, and approved language should stay attached to the original asset.
- Rewrite the wrapper for the channel. Opening line, pacing, structure, caption style, and call to action should match how people use that platform.
- Localize more than language. Region, references, examples, units, compliance notes, and cultural assumptions often matter as much as translation.
- Set adaptation limits. Some assets travel well. Others lose meaning when compressed, clipped, or stripped of context.
A publisher covering finance might turn one reported feature into a site article, a subscriber briefing, a short-form video, and a region-specific email version for UK readers. The argument stays consistent. The framing changes. UK readers may need different terminology, examples, and regulatory references than US readers. That is localization as an editorial decision, not a last-minute translation task.
The same logic applies to creators. A course instructor may extract one strong lesson from a long video, but the YouTube version can afford setup and proof, while the Instagram version needs the payoff in the first seconds. Email subscribers may respond better to a plain-language takeaway and one concrete action step. Same knowledge. Different packaging. Better fit.
This is also where teams waste time if governance is weak. Without clear ownership, five people make five versions of the same asset, each with slight wording changes and no record of which one was approved. Search suffers, brand consistency slips, and sales or audience teams stop trusting the library. A good knowledge management system prevents that drift by connecting variants back to the source and recording where each version is approved for use.
Adaptation expands reach. Localization expands relevance. Together, they turn stored knowledge into channel-ready inventory that can keep earning across platforms, audiences, and markets.
9. Content Performance Analytics and Insight Extraction
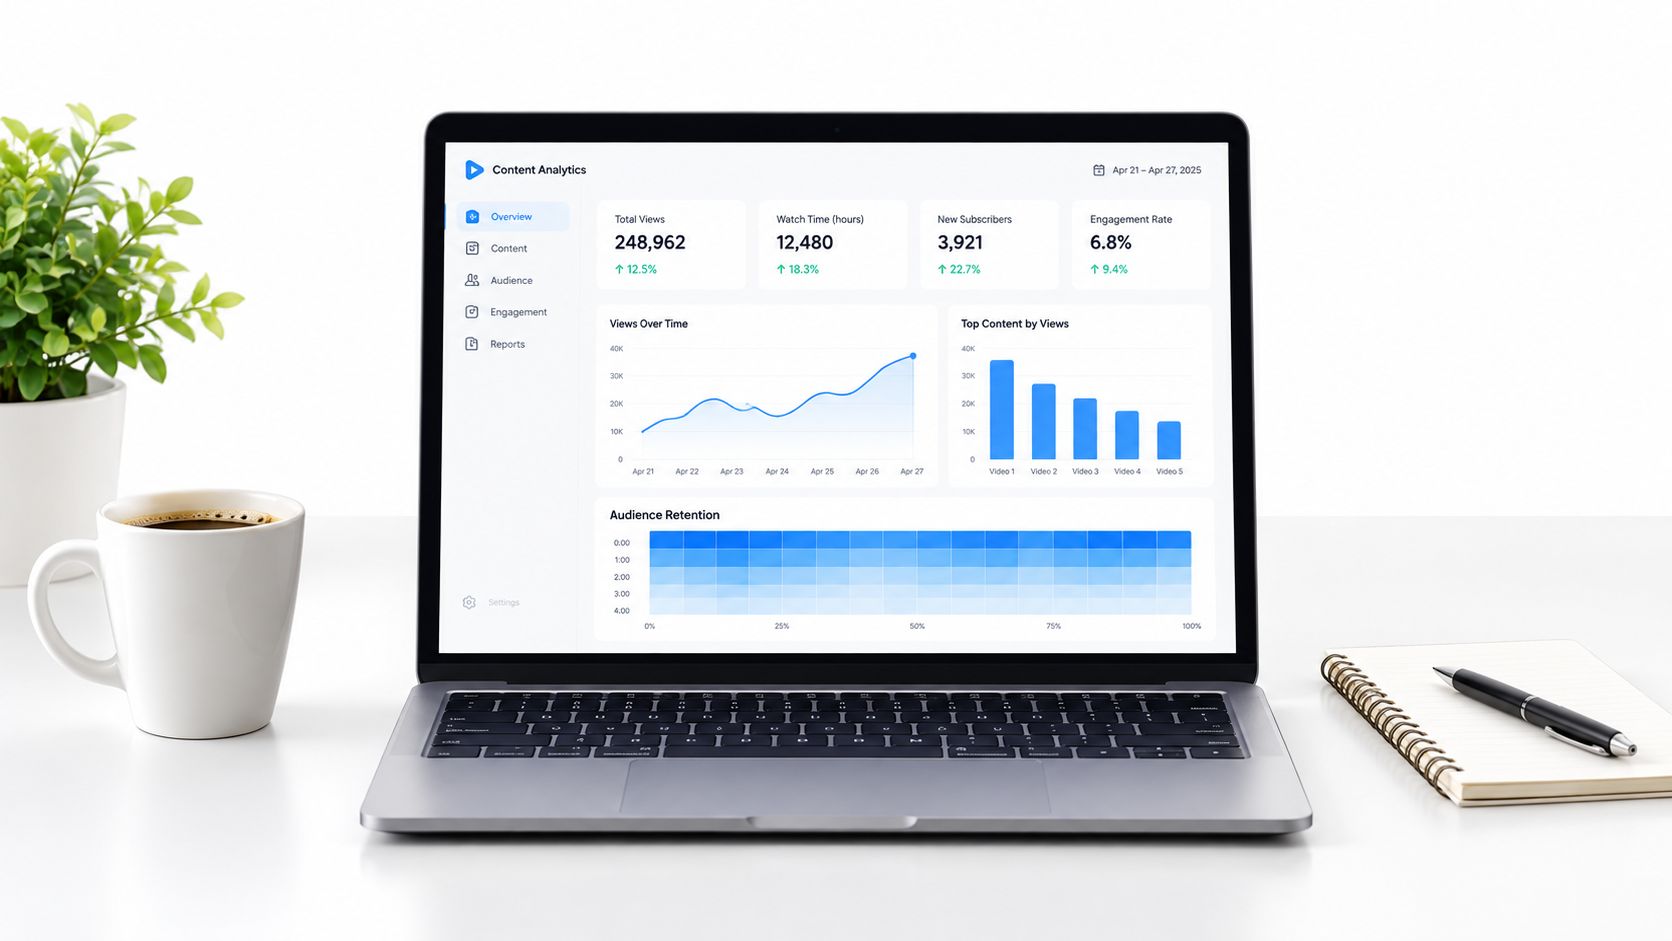
Strong archives do not earn on storage alone. They earn when performance patterns shape what the team republishes, updates, bundles, retires, and turns into the next asset.
That makes analytics part of knowledge management, not a reporting add-on. If a creator sees that a two-year-old tutorial still holds attention and drives email signups, that piece belongs on an update queue, not in a forgotten folder. If a publisher finds that three separate articles on the same topic keep attracting search traffic, that is a signal to build a package, refresh the metadata, and assign a clear owner for follow-on coverage.
The metric mix matters. A dashboard full of impressions can flatter a weak system. Revenue-enabling teams track signs of utility and reuse. They want to know which source assets keep spawning new work, which topics reduce research time because the background is already organized, and which formats attract attention but fail to support subscriptions, leads, or downstream editorial value.
An independent benchmark summary from HDI found that organizations often judge user-facing knowledge programs with outcome measures such as customer satisfaction, adoption, escalation deflection, article feedback, and reuse (HDI KM benchmark summary). Content teams can apply the same logic. Measure whether knowledge gets used, reused, found quickly, and kept current.
A simple review cadence works better than a giant reporting ritual. I have seen teams get more value from a 30-minute monthly review of ten assets than from a quarterly slide deck no one uses. Look at the library through three lenses.
First, inspect individual assets. Identify the pieces worth expanding into a series, refreshing with new examples, or consolidating with related material.
Second, inspect patterns across assets. Repeated wins around a topic, angle, contributor, or format usually point to a taxonomy or packaging opportunity, not just a one-off success.
Third, inspect the production path. Track which workflows turn one strong source into reliable multi-platform output without extra editorial cleanup. That is the operating-system view. It connects library organization, searchability, lifecycle rules, collaboration, and repurposing back to business value.
Good insight extraction changes decisions. It helps teams stop producing from scratch when the archive already contains the raw material for the next article, video, briefing, or sales asset.
10. Audience Segmentation, Feedback Integration, and Targeted Delivery
Generic delivery wastes good content.
A strong knowledge system does more than store assets and make them searchable. It helps teams match the right asset, format, and framing to the right audience at the right moment. That is where knowledge management starts acting like a revenue-enabling content operating system, not a filing cabinet. The archive stops being static inventory and starts supplying sales enablement, audience growth, retention, and repurposing decisions across channels.
That shift usually becomes obvious in production. A creator may see that introductory videos pull in new subscribers, while technical breakdowns keep experienced viewers engaged longer. A publisher may cover one subject in reported features, short explainers, newsletter summaries, and member-only analysis because each format serves a different level of reader intent.
The operational question is simple. Can the team identify those differences inside the library, then act on them without rebuilding the workflow every time?
Recent APQC research points to a maturity gap that matters here. APQC reports that organizations still prioritize better search and discovery, clearer measurement of KM impact, and strategy updates. The same findings show many teams remain early-stage and struggle to access relevant knowledge (APQC KM priorities and maturity findings). If internal teams cannot retrieve the right knowledge by audience, role, or use case, targeted external delivery usually stays manual and inconsistent.
A practical fix is to segment the library in ways editors, marketers, and producers can maintain. Useful segmentation often includes experience level, industry, job role, buying stage, content goal, and preferred format. Too many fields create tagging debt. Too few fields flatten important differences and make repurposing harder.
Feedback should also change the structure of the system, not just inspire the next piece. Comments, support questions, community threads, newsletter replies, subscriber polls, and sales call notes all reveal where the library needs a new segment, a sharper label, or a different packaging path. When those signals stay trapped in separate tools, teams keep hearing the audience without improving delivery.
Here is what strong teams capture and use:
- Recurring audience questions that signal a missing explainer, update, or derivative asset
- Format preferences by segment, such as short clips for new followers or detailed briefings for buyers
- Objections, confusion points, and terminology differences that should change titles, tags, and summaries
- Distribution preferences, including newsletter tracks, member tiers, sales follow-up assets, or region-specific versions
The trade-off is real. Granular targeting improves relevance, but it also adds operational overhead. I have seen teams create audience matrices so detailed that no one could tag consistently. A simpler model usually works better. Start with the few segments that affect editorial choices, packaging, and distribution in a visible way.
For example, a podcaster can tag episodes by listener role and experience level, then turn the same source interview into a beginner recap, an operator-focused bonus cut, and a sales-friendly summary for sponsors or partners. A B2B content team can route one research asset into role-specific versions for executives, practitioners, and procurement stakeholders. A book publisher can package archive material differently for scholars, casual readers, and collectors, then deliver each package through the channel those readers already use.
That is the point of the system. Audience insight should change what gets stored, how it gets labeled, which version gets produced next, and who receives it first.
11. Content Series and Narrative Architecture
Series turn a content archive into a revenue-producing system.
A one-off asset can perform well, but a well-structured series does more useful work. It gives the audience a reason to return, gives the team a clearer production frame, and gives the archive reusable context. That matters when you want to turn one interview, report, or recurring theme into episodes, clips, newsletters, sales collateral, compilations, and later updates without rebuilding the logic each time.
The key is to design the series as an operating structure, not just a programming choice. A good series has a defined promise, a clear sequence, and known conversion points. Creators can use that structure to map what comes before the main asset, what supports it, and what gets repurposed after publication. Publishers can use the same structure to connect flagship pieces with sidebars, explainers, timelines, author Q&As, and archive resurfacing.
I have seen the opposite too. Teams publish recurring content with no stable naming, no chronology rules, and no record of how installments relate to one another. The audience may still see a pattern, but the internal system cannot support it. Search gets messier. Repurposing gets slower. New contributors have to guess what belongs where.
Build the architecture before volume piles up.
A practical series record usually includes the series name, the editorial premise, the intended audience action, the ordering logic, and the asset types attached to each installment. Then the team can answer useful operational questions fast. Which episode belongs in a starter playlist? Which article should be refreshed before the next release? Which past segment can be cut into a trailer, sponsor recap, or onboarding asset?
For example, a business creator might run a weekly "operator teardown" series. Each installment can produce a full video, short clips by tactic, a newsletter summary, a swipe file entry, and a later year-in-review compilation. A trade publisher covering a policy beat can structure a series around one legislative shift, then connect each new piece to prior context, expert reactions, and a final guide once the story matures. In both cases, the series is not just content packaging. It is the retrieval and repurposing map.
A few rules keep that map usable:
- Use one permanent naming convention for the series and stick to it
- Tag installments by sequence, role, and stage in the broader narrative
- Record the prerequisite assets or context pieces each installment depends on
- Mark which assets are recap-ready, update-ready, or suitable for compilation
That structure comes with a trade-off. Tight narrative architecture improves reuse and planning, but it can also make a team too rigid if every idea has to fit an existing arc. Leave room for standalone pieces and experiments. The goal is a series system that creates momentum, not one that traps the editorial calendar.
Done well, series architecture helps teams get more from what they already know. It connects discovery, production, reuse, and monetization in one frame. That is what makes knowledge management useful at the operating level, not just tidy at the library level.
12. Experimentation Culture and Iterative Content Testing
Testing is how a content archive turns into a revenue system.
A library full of finished assets has value. A library that also stores what changed, why it changed, and what happened next is far more useful. That record helps creators commission the right spinoff, helps editors choose the right update angle, and helps commercial teams package proven themes instead of guessing.
The practical shift is simple. Treat experiments as knowledge objects, not side notes.
A solo creator might test three openings for the same YouTube topic, then learn that a specific promise works for subscribers but loses new viewers. A publisher might test whether expert-led headlines outperform issue-led headlines for a policy newsletter, then use that result to shape future briefs, homepage packaging, and social cutdowns. In both cases, the point is not just to improve one asset. It is to improve the next ten.
That only works if the test can be found later.
Instead of another paragraph-list-paragraph workflow, use a lightweight experiment record attached to the content itself. Keep it short enough that the team will maintain it, but structured enough that the learning can be filtered across platforms, formats, and audience segments.
A useful record usually answers four questions:
- What variable changed? Title, hook, CTA, runtime, format, thumbnail style, guest profile, distribution slot
- What context matters? Audience segment, channel, series, topic cluster, stage in the content lifecycle
- What happened? The result in plain language, with the metric that mattered for that test
- What decision follows? Repeat, adapt, retire, or retest under different conditions
That last field matters more than teams expect. A test result without a decision becomes trivia. A test result tied to a next step becomes operating knowledge.
There is a trade-off here. More documentation improves reuse, but too much logging slows production and turns testing into admin work. I have found that teams get better compliance when they reserve full write-ups for meaningful tests and use a fast template for everything else. Save the detail for experiments that affect packaging standards, channel strategy, repurposing rules, or monetizable themes.
Good testing culture also protects teams from a common archive problem. They remember the winning asset and forget the conditions that made it win. Then they copy the surface pattern in the wrong context. A smart knowledge management system reduces that mistake by connecting the result to taxonomy, audience signals, search metadata, and the original asset trail.
Over time, that creates something more valuable than a stack of A/B tests. It creates a repeatable way to turn past content into sharper briefs, better adaptations, stronger distribution choices, and new inventory across platforms.
12-Point Knowledge Management Best Practices Comparison
| Approach | Implementation Complexity | Resource Requirements | Expected Outcomes | Ideal Use Cases | Key Advantages |
|---|---|---|---|---|---|
| Centralized Content Library Organization | High initial setup, moderate ongoing | DAM/CMS, migration effort, metadata standards, training | Unified searchable repository, faster reuse | Organizations with fragmented archives or large volumes | Reduces search time; enables reuse and AI insights |
| Layered Taxonomy and Smart Tagging Systems | High (design, governance) | Taxonomy design, tagging tools, AI-assisted tagging, governance | Rich discoverability, contextual content relationships | Personalized recommendations, complex catalogs | Sophisticated filtering; reveals thematic patterns |
| Search Optimization and Metadata Standards | Medium (schema + integration) | Metadata schemas, transcripting, search engine tooling | Reliable, repeatable retrieval and precise search results | Teams needing accurate asset retrieval and verification | Consistent retrieval; reduces duplicate work |
| Content Lifecycle and Asset Governance | Medium–High (policy & workflows) | Governance roles, status workflows, rights tracking, review schedules | Clear ownership, safe reuse, systematic archiving | Regulated industries, large distributed teams | Prevents misuse; clarifies responsibility and review |
| Documentation, Knowledge Base, and Process Standardization | Medium (documentation effort) | Wiki/tools, templates, version control, documentation owners | Faster onboarding, consistent quality and processes | Distributed teams, frequent hires, standardized production | Consistency; reduces rework and speeds onboarding |
| Collaborative Content Intelligence and Human-AI Collaboration | High (AI integration + oversight) | AI platforms, training data, validation workflows, data science support | Faster insight extraction, scaled recommendations | Large archives needing pattern discovery and scaling | Accelerates research; augments human judgment |
| Multi-Format Content Expansion and Atomization | Medium (workflow design) | Editing tools, templates, cross-functional skills, transcripts | Multiple derivatives per asset, improved ROI | Long-form creators, podcasts, educational content | Maximizes content value; meets diverse preferences |
| Cross-Platform Content Adaptation and Localization | Medium–High (platform expertise) | Localization services, platform specialists, analytics | Increased reach and platform-specific engagement | Multi-channel distribution, global audiences | Platform-optimized engagement; scalable reach |
| Content Performance Analytics and Insight Extraction | Medium–High (analytics stack) | Dashboards, integration, analytics expertise, data pipelines | Data-driven decisions, identify repurposing candidates | Optimization-focused teams measuring ROI | Removes guesswork; identifies high-value assets |
| Audience Segmentation, Feedback Integration, and Targeted Delivery | High (data & compliance) | Segmentation tools, surveys, CRM, privacy controls | Personalized content, better conversion and retention | Targeted marketing, community-driven creators | Higher relevance; audience-informed strategy |
| Content Series and Narrative Architecture | Medium (planning & structure) | Editorial planning, scheduling tools, series assets | Increased retention, repeat consumption, loyalty | Story-driven or educational content with episodic potential | Drives binge behavior; deeper engagement |
| Experimentation Culture and Iterative Content Testing | Medium (process + tooling) | A/B testing tools, experiment budget, analytics, documentation | Validated learnings, optimized content performance | Growth teams, creators seeking systematic optimization | Reduces risk; surfaces high-performing formats |
Turn Your Archive Into an Active Knowledge System
A valuable content library doesn't become useful on its own. Teams have to turn it into a working system. That usually starts with a smaller move than people expect. Centralize the assets you reuse most. Add a lean taxonomy. Define the metadata fields that make search reliable. Assign ownership so someone decides what gets refreshed, repurposed, archived, or retired.
Then tighten the operating rhythm. Document repeatable workflows. Let AI assist with tagging, clustering, and discovery, but keep humans responsible for judgment, quality, and final publishing decisions. Adapt assets deliberately across platforms instead of reposting blindly. Measure what creates value, not just what creates activity. If your search works, your metadata is clean, and your team knows what each asset is for, the archive starts producing ideas instead of friction.
A practical next-week sequence looks like this:
- Day one: Identify your top priority content bucket, such as flagship episodes, evergreen articles, or highest-value videos.
- Day two: Create a minimum metadata standard for those assets.
- Day three: Define five to ten core taxonomy dimensions your team will use.
- Day four: Mark lifecycle status and owner for the first batch.
- Day five: Document one repeatable repurposing workflow from source asset to derivative formats.
That cadence is manageable for a solo creator and still useful for a publisher with multiple contributors. The goal isn't to build a giant internal bureaucracy. It's to make old work usable, searchable, and connected to new production. Once that system exists, your archive starts acting less like storage and more like a research and production engine.
If your team wants to go deeper on AI-assisted retrieval, search-backed answers, and content discovery across large libraries, it also helps to understand how teams build a RAG pipeline around structured knowledge. The important part isn't the acronym. It's the discipline of grounding discovery in organized source material.
Contesimal fits naturally into this conversation because it's designed to help teams organize large multi-format libraries, classify and search historical assets, and collaborate around existing content. For creators, publishers, and content marketers trying to turn archives into new work, that's the promise of knowledge management best practices. Better systems don't just preserve what you made. They help you make the next thing faster and with more signal.
Contesimal helps creators and publishing teams classify, search, and collaborate across documents, podcasts, videos, and articles so existing libraries become easier to reuse. If you want your archive to support research, repurposing, and smarter production decisions, visit Contesimal and see how it fits your workflow.